
The Formula Could Have Failed
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: What actually makes training cheaper? – One thing has worked: stopping part of the training early saved about 7% with no loss of quality. Everything else tested has been matched by a simpler or cheaper method -- and in two cases the clever method was only winning because it was quietly being given more.
In plain English
What we asked. When a new model starts from a piece of an older one, the older one has to be trained first, and there is a best amount: too little and it does not help, too much and it costs more than it saves. We had a simple formula for the best amount, about 1.4 times as long as a new model takes to learn the task on its own. But the earlier test of it could not have failed, because of how the experiment had been set up.
What we found. So we built a test where it could fail: a new task, and training lengths chosen without reference to the formula, where the formula and its only rival pointed at different answers. The formula said 200 steps; the rival said 120. The best length was 200, where it took fewer than four new models to repay the older one's training, against more than six at 120.
Why it matters. So the formula has earned some trust, and finding the right training length now takes one short trial run and a multiplication instead of a sweep. The lesson worth copying: a prediction that matches every case you have tried is worth nothing until you have tried a case where it could have been wrong.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU, six seeds. The task was chosen by calibration on throwaway seeds, and the calibration, the exact-rung decision rule and the pilot were committed (7affbb4) before any measured run.
Program v2 Bucket R, item R12. Decisive computation: analysis/unscaled_ladder.pyanalysis/unscaled_ladder.jsonpython analysis/unscaled_ladder.py (about forty minutes on a throttled laptop CPU); --reuse re-derives every endpoint from the saved series.
The question
R5 found the donor break-even U-shaped in donor length, so the cheapest donor is not the best one and finding the best costs a sweep. R9 found one constant, 1.40 times the receiver control's transition time, that predicted the optimum on both committed ladders exactly -- and could not have failed: R5's ladder is P8's scaled by that same quantity, so "a fixed multiple of the transition" and "the same rung index" landed 0.037 of a rung apart. R14 counted it as one of the archive's three known designs that decided their own answer.
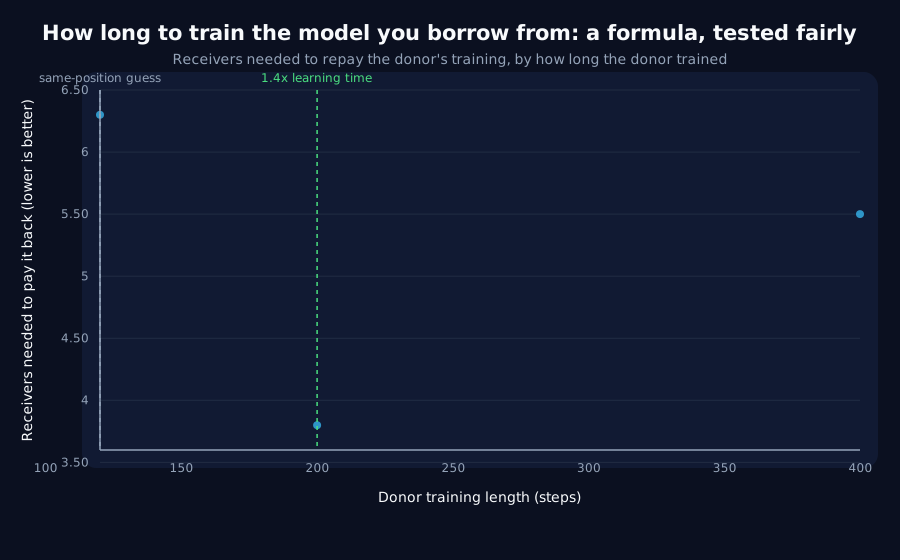
The fix is a ladder the predictor had no hand in. P8's absolute rungs, 20 to 400, unscaled, on a task whose transition sits between the two existing ladders'. Calibrated on throwaway seeds before the run: dispatch-copy-wide-vocab reaches the task criterion at about 150 steps. There the multiple predicts the 200 rung and the rung index predicts 120.
Decision rule, fixed before execution: the optimum is the rung with the lowest break-even (receivers needed for an own-donor to pay for itself, R5's definition, only where the head start excludes zero). The hypothesis whose rung equals the measured optimum wins; if neither, both lose. Because the two predictions are adjacent rungs, "within one rung" -- R9's tolerance -- would have accepted either, and is not used.
Kill test (the item's own): the predictions do not separate by at least one rung. Checked in code from the measured control, before the optimum is read.
The predictions separated
The measured control reaches the criterion at 153.3 [143.6, 163.1] steps. The multiple predicts 1.40 x 153.3 = 215, nearest rung 200; the rung index predicts 120. One rung apart, so the kill test does not fire and the ladder can decide.
Result: the optimum is at 200 -- the multiple wins
| Donor length | Receiver head start | Receivers to pay back | Donor accuracy |
|---|---|---|---|
20 | +22.5 [+11.6, +33.4] | no saving | 0.082 |
40 | +25.8 [+12.8, +38.9] | no saving | 0.150 |
60 | +17.5 [+4.8, +30.2] | no saving | 0.186 |
80 | +6.7 [+0.3, +13.0] | no saving | 0.226 |
120 (rung index) | -19.2 [-30.4, -8.0] | 6.3 | 0.298 |
200 (the multiple) | -53.3 [-65.1, -41.5] | 3.8 | 0.388 |
400 | -73.3 [-83.7, -63.0] | 5.5 | 0.493 |
The best donor is 200 steps long, exactly where 1.40 x the control's transition put it, and the rung-index hypothesis loses by a factor of 1.7 in break-even. The U-shape reproduces on a third task: short donors delay the receiver, the optimum is in the middle, and the longest donor, though it gives the largest head start, costs more than it saves relative to 200. Short donors hurt here, as they did in P8: a donor must get past its own transition before it helps at all.
What this changes
R9's formula now carries evidence. On two scaled ladders it could not fail; on this unscaled one it could, and it picked the right rung against the one rival that had matched it everywhere else. The practical rule for this programme's donor economics:
Train the donor for about 1.4 times as long as a receiver takes to learn the task on its own. Measuring that takes one control run, which the receiver needs anyway.
The seven-rung sweep that R5 needed to find its optimum becomes one control run and a multiplication.
What stands
- The kill test does not fire: the two predictions separate by a rung on an unscaled ladder.
- The multiple wins: the optimum is at
200, the rung1.40 x 153.3predicts; the rung index's120pays back at6.3receivers against3.8. - R9 is resolved by banner: its predictor has now passed a test it could have failed.
- The U-shape holds on a third task.
Limits
- The optimum is read from mean head starts. The break-even difference between the
200and400rungs (3.8against5.5) has no interval of its own; the head starts at both exclude zero by a wide margin, and the ranking between them is a ratio of means. - One test of an exact-rung prediction on adjacent rungs. A single success is evidence, not a calibration: the constant
1.40was fitted on two ladders and confirmed on one. - Six seeds, one width, one learning rate. The constant is stated for this setting.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- accuracy
- The fraction of answers a model gets right on questions it was not trained on.
- calibrated
- A model is calibrated when its confidence matches how often it is right: answers it gives with 90% confidence should be right about 90% of the time.
- calibration
- Working out an instrument's settings from runs whose answer you already know, so it can be used on a run whose answer you do not.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- learning rate
- How big a step training takes each time it updates the model. Too small and nothing happens; too big and it never settles.
- seed
- The number that fixes all the randomness in a training run. Same seed, same run. Running several seeds is how you tell a real effect from a lucky one.
- width
- How many internal numbers a model uses at each layer. The usual way we vary model size in these experiments.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.