
Depth Costs Most of the Budget
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: What actually happens at the moment a model learns? – It builds machinery rather than selecting it, working through the task in a reproducible order and trying a simpler wrong rule on the way. The visible training curve cannot tell you which is happening.
In plain English
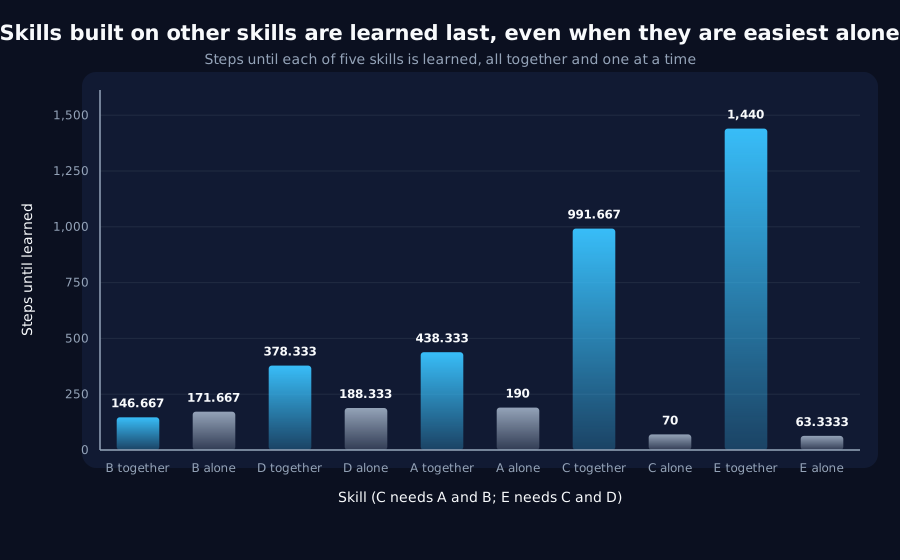
What we asked. Do models learn skills in the order of what depends on what, or in the order of what is easiest? We built a task with five skills: three simple look-ups, one that combines two of them, and one that combines that combination with the third look-up. We made the two combined skills the easiest of all when trained on their own, so the two explanations predict opposite orders.
What we found. On their own, the combined skills were learned fastest. Trained together, they came last, in exactly the order of what depends on what: the look-ups first, then the first combination, then the second. The deepest skill, learned alone in about 60 steps, was mostly not learned at all in 1,500 steps when it had to be built from its parts.
Why it matters. We had set a rule in advance that every skill must actually be learned before we would run the formal test, and the deepest one was not, so this is a clear pattern rather than a tested result. The practical point stands anyway: stacking skills on skills can cost far more training than any one of them costs alone. A longer run is next.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU, six seeds. Operationalised and committed (d6cf142) before any run.
Program v2 Bucket O, item O6. Decisive computation: analysis/prerequisite_graph.pyanalysis/prerequisite_graph.jsonpython analysis/prerequisite_graph.py (about forty-five minutes on a throttled laptop CPU); --reuse re-derives every endpoint from the saved series.
The question
P3 planted three skills -- retrievals A and B, and C = A + B made easy in isolation -- and found acquisition order followed the dependency, not isolated difficulty: C, the easiest alone, arrived last. O6 asks the question P3 could only begin: does acquisition order recover a deeper, branching graph?
The planted graph: retrievals A, D, B at increasing distance (depth 0); C = A + B (depth 1); E = C + D (depth 2). C and E are both made easy in isolation (adjacent operands, no retrieval), so depth and isolated difficulty make opposite predictions.
Kill test, fixed before execution: per seed, the rank correlation between acquisition step in the composite task and planted depth; fires if its mean's interval does not exclude zero.
Precondition, fixed before execution: every skill acquired in the composite task on at least four of six seeds, or an ordering over skills that never fire is not interpreted.
Result: the precondition fails -- the deepest skill was not learned in the budget
Acquisition step (first step past halfway from chance to perfect, and staying there), composite task and alone:
| Skill | Depth | In the composite task | Seeds | Alone | Seeds |
|---|---|---|---|---|---|
B | 0 | 146.7 | 6/6 | 171.7 | 6/6 |
D | 0 | 378.3 | 6/6 | 188.3 | 6/6 |
A | 0 | 438.3 | 6/6 | 190.0 | 6/6 |
C | 1 | 991.7 | 6/6 | 70.0 | 6/6 |
E | 2 | 1440.0 | 2/6 | 63.3 | 6/6 |
E was acquired on only two of six seeds within 1500 steps, so the kill test is not computed, as fixed in advance. That is the result of this record: a skill two levels deep, which alone is learned in 63 steps -- the fastest of all five -- is not learned at all in 1500 steps on most seeds when it has to be built from its prerequisites.
What the order looks like, described and not inferred
The per-seed test is not run, so the following is description only:
- Every depth-
0skill is acquired before the depth-1skill, and the depth-1skill before the depth-2one, on every seed where all were acquired. The mean orderB, D, A, C, Eis the planted depth order exactly. - Isolated difficulty says the opposite for the composites: alone,
E(63) andC(70) are the two fastest skills; in the composite they are the two slowest. - Within depth
0, the "hardest" retrieval comes first:B, the token furthest back, is acquired at147steps, beforeD(378) andA(438). Distance did not order the retrievals; the first token of a sequence is evidently the easiest one for this GRU to hold.
This is P3's finding extended one level, pointing the same way -- and it is not a test of it, because the precondition written to protect the test failed.
What stands
- The precondition fails; the kill test is not computed.
Eis acquired on2of6seeds. - Descriptively, acquisition follows planted depth exactly, and isolated difficulty the other way -- P3's pattern, one level deeper.
- A composite two levels deep is not learned in
1500steps though alone it is learned in63: the cost of depth, in this task, is most of the budget. - Generates O11: the same design with a budget long enough for
E, the ordering test run as written.
Limits
- One budget. The failure is a budget, not a verdict; O11 exists to remove it.
- Retrieval position was meant as a difficulty ladder and is not one (
Bis fastest), so depth-0skills are not ordered as designed. That does not affect the depth test, which compares layers. - Order, not edges. Whether acquisition recovers which skills feed which -- the graph itself, not only its layering -- is not tested here.
RESOLVED 2026-09-26 by O11. The same design run to5000steps reproduces this record's first1500steps exactly and acquires every skill on all six seeds (Eat1695on average). The test this record could not compute was then run as written: acquisition order follows planted depth on every seed (rank correlation+0.894, the maximum possible with three tied depth-0skills) and runs against isolated difficulty (-0.806). This record's failure was a budget, as its Limits said. Its text and numbers are unchanged.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- GRU
- Gated Recurrent Unit. A compact design for processing sequences one item at a time, with internal switches controlling what it keeps in memory.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- rank
- How many independent directions a set of numbers really uses. A low-rank structure is one that looks high-dimensional but is actually simple underneath.
- seed
- The number that fixes all the randomness in a training run. Same seed, same run. Running several seeds is how you tell a real effect from a lucky one.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.