
Which Weights Carry the Transition?
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: Which parts of a model actually matter? – The parts that move most are not the parts that matter, and no single component is required -- the model routes around every freeze. What a part is worth shows up only when you remove it.
In plain English
What we asked. A model has distinct internal components. When it suddenly learns, which of them is actually doing the work?
What we found. Motion and necessity turn out to be different components. The parts that change most are not the parts the model needs. And no single component is required at all: freeze any one of them and the model routes around it and learns anyway.
Why it matters. The obvious way to find the important part of a model is to look for what changes. This shows that is the wrong instrument, because the two questions have different answers. It also shows the model is far more redundant than the tidy story suggests.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU, 40 training runs, no GPU, no cost.
Program v2 tier 3, item D1. Decisive computation: analysis/transition_anatomy.pyanalysis/transition_anatomy.jsonpython analysis/transition_anatomy.py in about twenty minutes on a throttled laptop CPU.
The question
The representation expands at the transition. Which weights move to produce that?
E3 sharpened this a great deal. The expansion is present in every gated recurrent cell tested and absent in attention and in an ungated cell, so multiplicative gating is the suspect. A GRU stacks three gates in each recurrent matrix: reset, update, candidate, 48 rows each at width 48, so "which matrix" becomes answerable as "which gate".
Two parts, because observation and causation are different questions.
Part A: where the motion is
Per-group update norms through training, aligned to each run's own transition, and reported relative to each group's own weight norm, because an absolute update norm mostly measures how many parameters a group has. The window is ±40 steps around the transition.
| Group | In window | Elsewhere | Concentration |
|---|---|---|---|
| gate: update | 0.06624 | 0.02429 | 2.73x |
| gate: candidate | 0.06161 | 0.02741 | 2.25x |
| gate: reset | 0.05436 | 0.02740 | 1.98x |
| head | 0.05096 | 0.01465 | 3.48x |
| final_norm | 0.01781 | 0.00355 | 5.01x |
| embedding | 0.00842 | 0.00492 | 1.71x |
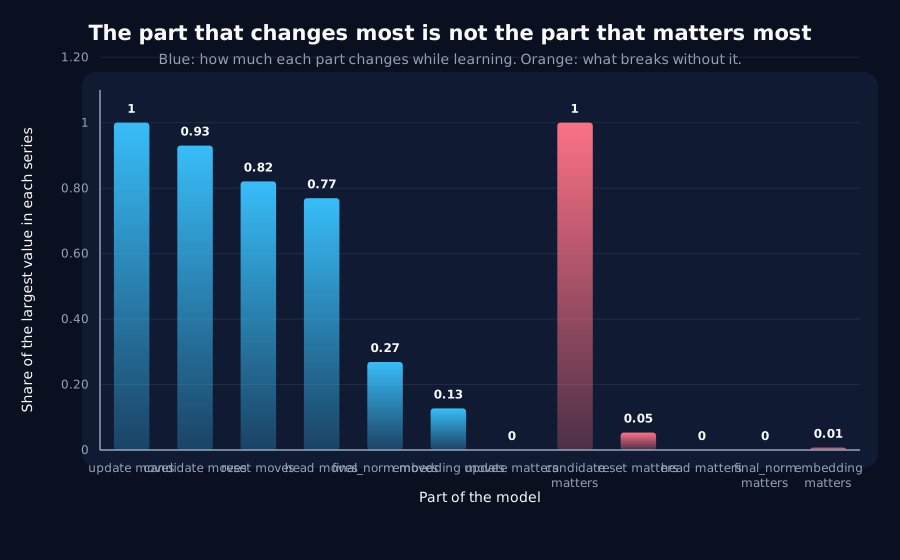
Motion localises, in both senses. It concentrates in time, every group moves 1.7x to 5x faster inside the transition window than outside it, and in place: the update gate moves 7.9x faster than the embedding.
The kill test, "motion is spread uniformly across matrices and time", does not fire.
Part B: what is load-bearing
Freeze one group at a time and ask what it costs. Every arm runs with weight_decay = 0, including the control, because AdamW's decoupled decay shrinks a parameter whether or not it has a gradient, and a "frozen" group under the project's usual 0.01 would drift toward zero and measure decay rather than freezing.
| Frozen group | Learned | Accuracy lost | Transition width | Expansion remaining |
|---|---|---|---|---|
| gate: candidate | 5/5 | +0.2328 | 3.47x | 56% |
| gate: reset | 5/5 | +0.0124 | 1.84x | 106% |
| embedding | 5/5 | +0.0017 | 1.02x | 101% |
| gate: update | 5/5 | -0.0013 | 1.00x | 121% |
| final_norm | 5/5 | -0.0024 | 1.02x | 102% |
| head | 5/5 | -0.0043 | 1.22x | 98% |
Nothing is fatal. All six freezes still transition in 5 of 5 runs. The network routes around every single-group freeze, which is worth stating plainly because it is the kind of result that would be invisible under a pass/fail reading.
The result: motion and necessity dissociate
The update gate moves fastest in the transition window and costs nothing to freeze: its arm is a hair more accurate than the control and expands 21% more. The candidate gate moves less and is the expensive one: freezing it costs 23 percentage points of accuracy, makes the transition 3.5x wider, and removes 44% of the expansion.
Where the parameters move is not where the work is being done. That is the entire reason Part B exists, and a study that ran only Part A would have named the update gate and been wrong.
The ordering is also informative in its own right. The candidate gate is the GRU's proposal for a new hidden state, the content of what gets written. The update gate controls how much of that proposal is admitted. That the content matters more than the admission rate is not obvious in advance, and it is the first mechanistic handle this program has on what gating contributes.
Two corroborations of earlier results
- Freezing the embedding costs
0.0017. Archive mining found the embedding unchanged to four decimal places under the geometry penalty; here it is confirmed to be doing almost nothing at the transition either, from the causal side. - **Freezing the head costs nothing** (
-0.0043, i.e. very slightly better). Combined with F3, where freezing the recurrence was devastating, the pair is clean: the recurrence is load-bearing and the readout is not. A model with a random, never-trained output layer still reaches0.9954.
Limits
- One architecture (GRU), one task, one width, five seeds. The gate decomposition is GRU-specific by construction; an LSTM has four gates and would need its own version, which E3's result now makes worth running.
- Freezes are single-group. Pairs are untested, and "no single group is required" is compatible with some pair being required.
- Part A measures update norms, not directions. Two groups moving equally far may be doing very different things, and a rotation that leaves the norm unchanged is invisible here.
- The
weight_decay = 0control makes Part B internally consistent but not directly comparable to the project's archived runs, which all used0.01.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- accuracy
- The fraction of answers a model gets right on questions it was not trained on.
- AdamW
- A widely used training algorithm that adapts how big a step it takes for each individual parameter. The default in most modern AI training.
- architecture
- The blueprint of a model: what components it has and how they connect. Two models can be the same size and completely different architectures.
- freezing
- Stopping one part of a model from changing while the rest carries on learning. A way of asking what that part contributes, by taking it away.
- gated
- A design where the model has explicit internal switches deciding what to remember and what to discard at each step. GRUs and LSTMs are gated; plain recurrent networks are not.
- gradient
- The direction and amount by which each of a model's internal numbers should change to do slightly better. Training is repeatedly following it.
- GRU
- Gated Recurrent Unit. A compact design for processing sequences one item at a time, with internal switches controlling what it keeps in memory.
- hidden state
- The model's working memory: the internal numbers it carries from one step of a sequence to the next.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- LSTM
- Long Short-Term Memory. An older and larger relative of the GRU, also gated, also for sequences.
- parameters
- The adjustable numbers inside a model. Training is the process of setting them. Model size is usually quoted as a count of these.
- recurrent
- A design that reads a sequence one item at a time, carrying memory forward. The main alternative is attention, which looks at everything at once.
- seed
- The number that fixes all the randomness in a training run. Same seed, same run. Running several seeds is how you tell a real effect from a lucky one.
- width
- How many internal numbers a model uses at each layer. The usual way we vary model size in these experiments.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.