
A Small Dose Does Little
Ongoing research. This is an experimental result from active work, not a settled conclusion. The numbers are what we measured and the method is described so you can judge it, but the programme is still running and later experiments may revise what it means.
A note on the language in these records. This is a working laboratory notebook for research into training AI models more cheaply and efficiently, so you will read that an approach did not work, that a result did not hold up, or that one method was worse than another. That is the research doing its job, not a verdict on the engineering we deliver to clients. Ruling an approach out is how the search narrows, and these are the pages that teach us the most: nearly every technique we now rely on came from understanding why something else fell short. Testing our own ideas at least as hard as anyone else's is the point of publishing them. More about this programme and why we run it.
Part of a bigger question: Which parts of a model actually matter? – The parts that move most are not the parts that matter, and no single component is required -- the model routes around every freeze. What a part is worth shows up only when you remove it.
In plain English
What we asked. A new model can start from a mix of its own starting weights and a trained donor's. We had found that a small share of an unhelpful donor does no harm, while the whole thing does a lot of harm. That raised two questions: is that true for other donors, and can a partial mix of a helpful donor ever beat using all of it?
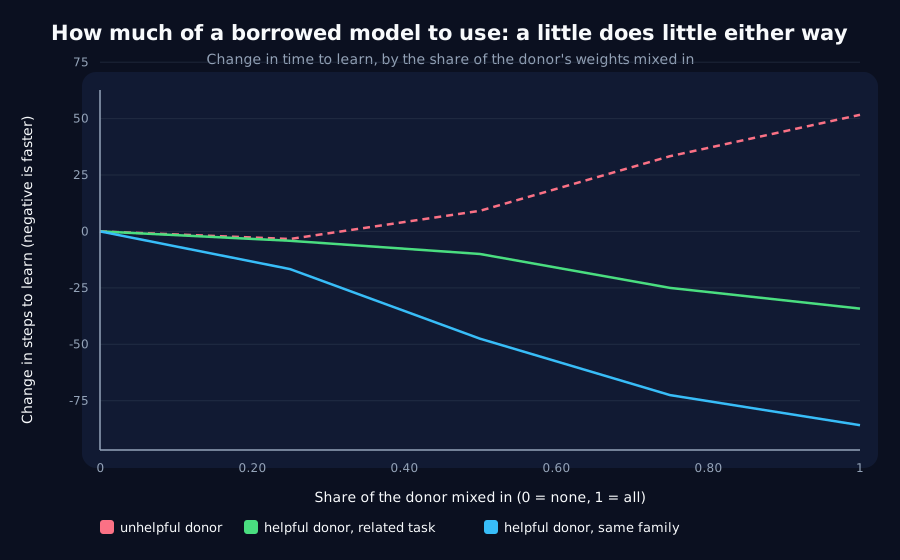
What we found. The first answer is yes: on a different unhelpful donor, a quarter share was harmless and even slightly helpful, while the whole donor slowed learning a lot. The second answer is no: for two helpful donors, every partial mix was slower than using the whole donor, and the benefit grew steadily with the share.
Why it matters. Put together, a small share of any donor does little, good or bad; most of the effect comes in the second half. So if a donor helps, use all of it, and a small dose of an unhelpful one is safe but not worth the trouble. A related idea we had queued, that part of a long-trained donor might be cheaper, turned out to rest on a mistake: you still pay to train the whole donor.
The rest of this page is the technical record: the design, every number, and the limits. It is written for a reviewer, and you do not need it to have understood the result above.
New here? How to read a research record
- Start at the verdict. Every record states, before the experiment was run, what result would have made us abandon the idea. That is the "kill test". Then it says whether the test fired. Nothing gets reinterpreted after the fact.
- Numbers in square brackets are uncertainty.
23.4 [18.1, 28.7]means our best estimate is 23.4 and the true value is probably somewhere in that range. If a range includes zero, we cannot claim an effect. - Results that rule an idea out are kept. Roughly half of what is published here says an approach did not work, including plenty of our own. Those pages are the output, not a shortfall: knowing which direction is a dead end is what lets the next experiment go somewhere better, and most of what we now rely on came out of understanding why something else fell short. Work that only publishes what worked is not measuring anything.
- Read the Limits section. Every record ends with what it does not show. It is the most honest part of any experiment and usually the shortest.
- Pro tip: the figures near the top are designed to carry the result on their own. If you read nothing else, read the caption under each one, which says what it shows and what to take from it.
EXPLORATORY. Not a preregistered study. Local CPU, six seeds. The kill test was written on 2026-09-04 and its operational form committed with the pilot (b89bfab) before any run.
Program v2 Bucket R, item R7. Decisive computation: analysis/graft_dose.pyanalysis/graft_dose.jsonpython analysis/graft_dose.py (about an hour on a throttled laptop CPU); --reuse re-derives every endpoint from the saved series.
The question
R4 found that grafting a wrong donor's recurrent weights harms a receiver superlinearly in how much is grafted: on running-count into dispatch-copy-8lag, a quarter costs +0.0 [-3.3, +3.3] and the whole +145.0. Two questions follow, and a third arrived with R6's screen:
- Part A. Is the free quarter a property of that one pair, or does it reproduce?
- Part B. Is there anything useful below full strength -- does a partial blend of a helpful donor ever beat the full graft? If so, blending is a tuning knob.
- The third angle. R6's screen now rejects harmful donors reliably. If a rejected donor is the only one you have, is there a dose at which it is net positive?
Kill test, fixed before execution: the free region does not reproduce, or a partial graft never beats the full one for a helpful donor.
Prior recorded in advance: moderate; R4's tolerance region predicts small grafts are nearly free both ways, so a partial helpful graft should be weaker rather than better.
Anchor, in code, passed exactly: a full-strength blend is R6's graft, and on R6's first seed it reproduces R6's committed accuracy series exactly.
Design
R4's blend: the donor's recurrent weights mixed with the receiver's own weights at the graft step (step 30), at fractions 0.25, 0.5, 0.75, 1.0. Three pairs from R6's pool, each against its own control, under L7's published criterion:
| Pair | Donor | Receiver | Kind |
|---|---|---|---|
| harmful | running-count | delayed-copy | R6 measured it harmful; a second pair for R4's curve |
| helpful-copy | noisy-copy-15 | delayed-copy | helpful, related |
| helpful-dispatch | dispatch-4lag | dispatch-copy-8lag | helpful, same family |
Result: the kill test fires -- on Part B
Change in time to the criterion against each seed's control (negative is faster):
| Pair | 0.25 | 0.5 | 0.75 | 1.0 |
|---|---|---|---|---|
| harmful | -3.3 [-6.0, -0.6] | +9.2 [+5.2, +13.1] | +33.3 [+29.0, +37.6] | +51.7 [+47.4, +56.0] |
| helpful-copy | -4.2 [-6.3, -2.0] | -10.0 [-14.7, -5.3] | -25.0 [-28.3, -21.7] | -34.2 [-39.3, -29.0] |
| helpful-dispatch | -16.7 [-24.6, -8.8] | -47.5 [-65.3, -29.7] | -72.5 [-86.9, -58.1] | -85.8 [-94.9, -76.8] |
Part A -- the free region reproduces. On a second harmful pair, the quarter graft costs nothing; in fact it helps slightly (-3.3, interval excluding zero), while the full graft costs +51.7. The harm is superlinear again: +9, +33, +52 as the fraction rises.
Part B -- a partial graft never beats the full one. For both helpful donors every fraction below 1.0 is slower than the full graft, by +9.2 to +69.2 steps, every interval excluding zero. The benefit grows steadily with dose all the way to the whole donor. Blending is not a tuning knob.
The third angle -- yes, barely. A screen-rejected donor is net positive at a quarter dose: -3.3 steps. A real effect, and small enough that the practical advice is still "use a helpful donor, and if you have none, use none".
What the three curves say together
Small doses do little, in either direction. A quarter of a helpful donor buys 4-17 steps where the whole buys 34-86; a quarter of a harmful one costs nothing where the whole costs 52. R4's "free quarter" is not a special safe zone for harmful donors: it is what a small blend of any donor does. The curves are convex in the same way -- most of the effect, good or bad, arrives in the last half of the dose.
This closes R10. R10 asked whether a fraction of a long donor could beat the whole of a short one at matched donor cost; its own design said to run R7 first, because if a fraction never beats the whole at fixed length there is nothing to price. It never does. And R10's premise -- "a quarter of an 800-step donor costs half as much to produce" -- was mistaken: a partial graft still requires training the whole donor. R10 is withdrawn, with the reason recorded.
What stands
- The kill test fires: no partial graft of a helpful donor beats the full one, on either pair.
- The free quarter reproduces on a second harmful pair, where it is even slightly helpful.
- A screen-rejected donor is net positive at a quarter dose, by
3.3steps -- real and not worth having. - Small doses do little either way; the effect of a donor, helpful or harmful, arrives mostly in the second half of the dose. R10 withdrawn.
Limits
- One graft step (30), R4's early graft. A later graft overwrites more of what the receiver has built and might change the shape.
- Recurrent weights only, as in R4 and P1.
- Three pairs, one harmful and two helpful, six seeds each.
Terms on this page
Every piece of vocabulary this record uses, in plain language. Generated from the text above, so it cannot drift out of step with it.
- accuracy
- The fraction of answers a model gets right on questions it was not trained on.
- kill test
- A condition written down before running the experiment that says what result would make us abandon the idea. Fixing it in advance is what stops a disappointing result being reinterpreted as an encouraging one.
- recurrent
- A design that reads a sequence one item at a time, carrying memory forward. The main alternative is attention, which looks at everything at once.
- seed
- The number that fixes all the randomness in a training run. Same seed, same run. Running several seeds is how you tell a real effect from a lucky one.
Get new results as we publish them
Roughly monthly, one finding per email, in plain English first. Including the approaches that turned out not to work, which are usually the useful ones. No sales email.
Double opt-in: we send a confirmation link and add nobody who does not click it. One-click unsubscribe on every email.